Serve local LLMs from the cloud
Outdated: Written in September 2023. The
serverbinary is nowllama-server, llama.cpp builds with CMake instead ofmake, and the repository moved to github.com/ggml-org/llama.cpp. Hetzner has changed the CCX63 specs and prices since then. The post is kept as an archive; do not follow the commands as written.
This article serves as a continuation of my earlier post Try Llama2 Locally at No Cost. In this post, I will run the llama.cpp as a server in the cloud and use a quantized version of the Falcon 180B model (which is not a llama!). I will be able to interact with it using a web browser.
The llama.cpp has changed a lot since my previous post. The most important change is that ggmlv3 support is dropped in favor of the new GGUF format. Old models must be converted to the new format. The new format should be more efficient and faster. Also, the server example is now built by default, and so we don't have to use extra options to build the server.
Preliminary Works
I had to do some preliminary work before firing up the server and then to carefully choose the model and the server. As it will be a rather costly machine, I had to be ready and keep it online only as long as my experiments would run. I also had to prepare the experiment prompts that I will use to test the model.
Choosing the Model
To run the original Falcon 180B model, we will need a server with at least 400GB of RAM, as stated in the Hugging Face model card. This is a lot of memory and it is not easy to find one with that much memory. Keep in mind that by using llama.cpp we are using normal RAM and not the GPU VRAM.
Our next best option is to use a quantized version of the model. My source of quantized models is TheBloke. The quantized models are much smaller in size and require less memory to load. The tradeoff is that the quality of the model is lower in theory. In practice, the quality is still very good.
The model that we will use is Falcon-180B-GGUF. Based on the following table from TheBloke, we have to use the Q6_K model as it can fit in our RAM. It is important to remember that besides the RAM required to load the model, additional RAM is required for inference.
| Quantized | Max RAM required | Use case |
|---|---|---|
| Q2_K | 76.47 GB | smallest, significant quality loss - not recommended for most purposes |
| Q3_K_S | 80.27 GB | very small, high quality loss |
| Q3_K_M | 87.68 GB | very small, high quality loss |
| Q3_K_L | 94.49 GB | small, substantial quality loss |
| Q4_0 | 103.98 GB | legacy; small, very high quality loss - prefer using Q3_K_M |
| Q4_K_S | 103.98 GB | small, greater quality loss |
| Q4_K_M | 110.98 GB | medium, balanced quality - recommended |
| Q5_0 | 126.30 GB | legacy; medium, balanced quality - prefer using Q4_K_M |
| Q5_K_S | 126.30 GB | large, low quality loss - recommended |
| Q5_K_M | 133.49 GB | large, very low quality loss - recommended |
| Q6_K | 150.02 GB | very large, extremely low quality loss |
| Q8_0 | 193.26 GB | very large, extremely low quality loss - not recommended |
Choosing the Server
I have been using Hetzner for a long time for both professional and pet projects, so I will use their servers for these experiments too.
If you would like to try Hetzner, you can use my referral link https://hetzner.cloud/?ref=FFa8yIRRc09L and you will receive €20 in cloud credits.
The best cloud machine for our case has the following specs:
name: CCX63
vCPU: 48/AMD
RAM: 192GB
Disk: 960GB
Traffic: 60TB
Hourly: €0.5732
Monthly: €357
Note that I had to request an increase in the vCPU limit before I could start a 48-core server. This can be done easily from the Hetzner cloud console.
How to Run the Server
To prepare the server, we will install Git and the build tools.
apt update
apt install -y git build-essential
Then we need to clone the repo from GitHub. You may find more info about the project here.
git clone https://github.com/ggerganov/llama.cpp.git
cd llama.cpp
We download the model. Due to the limitation of the Hugging Face servers, we will need to download the model in parts, then merge the parts and put them into a single file.
mkdir -p models/180B

cd models/180B

wget https://huggingface.co/TheBloke/Falcon-180B-GGUF/resolve/main/falcon-180b.Q6_K.gguf-split-a \
    -O falcon-180b.Q6_K.gguf
wget https://huggingface.co/TheBloke/Falcon-180B-GGUF/resolve/main/falcon-180b.Q6_K.gguf-split-b \
    -O ->> falcon-180b.Q6_K.gguf
wget https://huggingface.co/TheBloke/Falcon-180B-GGUF/resolve/main/falcon-180b.Q6_K.gguf-split-c \
    -O ->> falcon-180b.Q6_K.gguf
Build the llama.cpp and run the server. I will use all the 48 cores of the server
and set the context size to 2048 (this is the maximum context size supported by the Falcon model).
# This will take a while
make

./server \
    --ctx-size 2048 \
    --threads 48 \
    --port 8080 \
    --model models/180B/falcon-180b.Q6_K.gguf
Immediately we will see the server starting to load the model. After a while the server will print to the console the progress of the loading.
llm_load_print_meta: format         = GGUF V2 (latest)
llm_load_print_meta: arch           = falcon
llm_load_print_meta: vocab type     = BPE
llm_load_print_meta: n_vocab        = 65024
llm_load_print_meta: n_merges       = 64784
llm_load_print_meta: n_ctx_train    = 2048
llm_load_print_meta: n_ctx          = 2048
llm_load_print_meta: n_embd         = 14848
llm_load_print_meta: n_head         = 232
llm_load_print_meta: n_head_kv      = 8
llm_load_print_meta: n_layer        = 80
llm_load_print_meta: n_rot          = 64
llm_load_print_meta: n_gqa          = 29
llm_load_print_meta: f_norm_eps     = 1.0e-05
llm_load_print_meta: f_norm_rms_eps = 1.0e-05
llm_load_print_meta: n_ff           = 59392
llm_load_print_meta: freq_base      = 10000.0
llm_load_print_meta: freq_scale     = 1
llm_load_print_meta: model type     = ?B
llm_load_print_meta: model ftype    = mostly Q6_K
llm_load_print_meta: model size     = 179.52 B
llm_load_print_meta: general.name   = Falcon
llm_load_print_meta: BOS token = 11 '<|endoftext|>'
llm_load_print_meta: EOS token = 11 '<|endoftext|>'
llm_load_print_meta: LF token  = 193 '
When we see the following message, the server is ready to accept connections.
llama server listening at http://127.0.0.1:8080
Most of the time it is a bad idea to open ports on the server. Instead, we may use an SSH tunnel to access the server from our local machine under localhost:8080:
ssh -L 8080:localhost:8080 root@<server-ip>
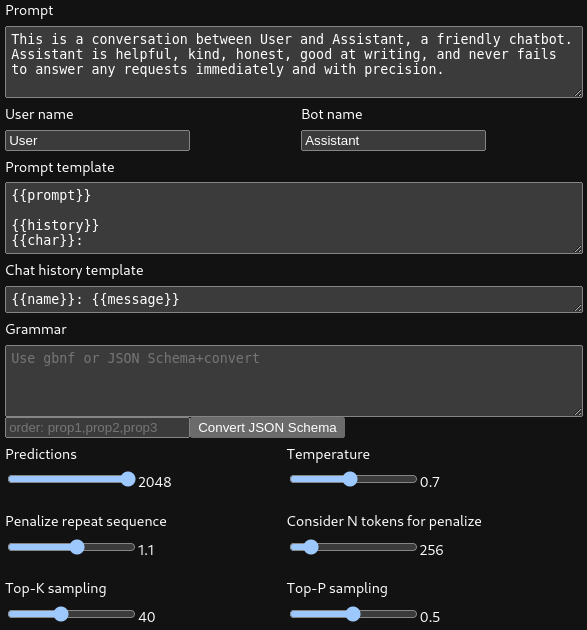
We will use the default options for the service. We have tried many options and it seems that the default options are indeed the best. The only thing that we should change is to increase the number of predictions to 2048 as we didn't want the output to be truncated.
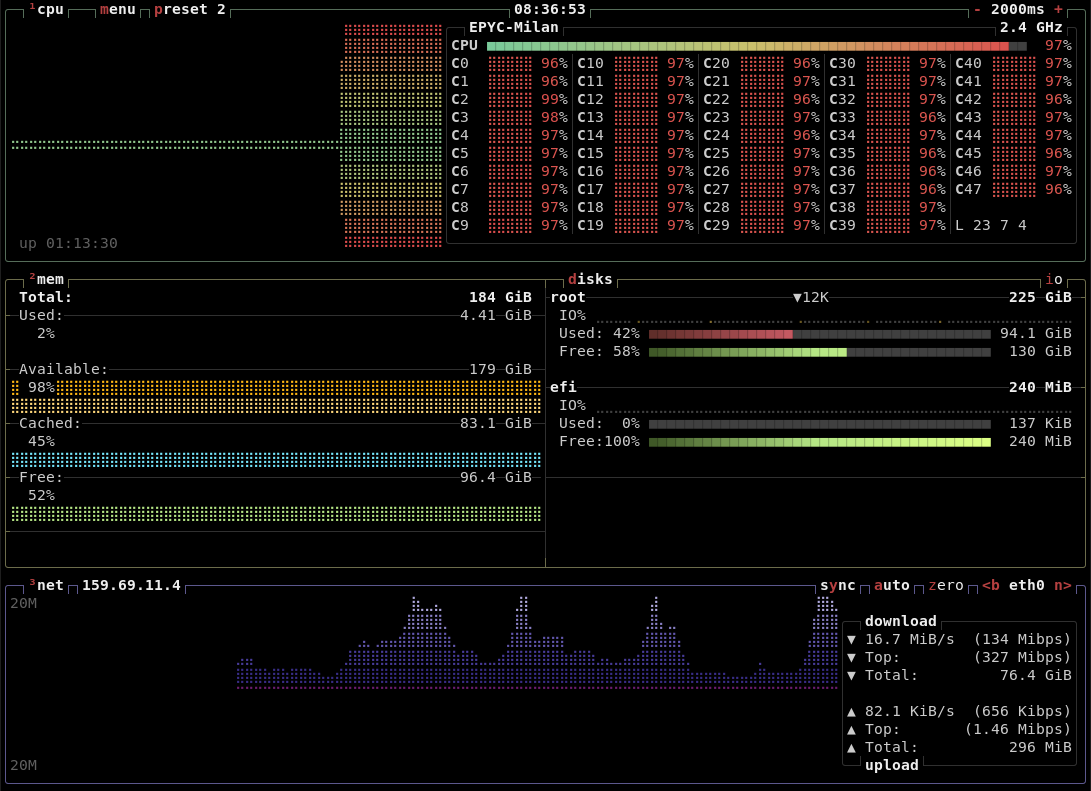
Running the inference does make the server busy. We use ~97% of the CPU and ~90% of the RAM. (btop failed to show the correct RAM usage)
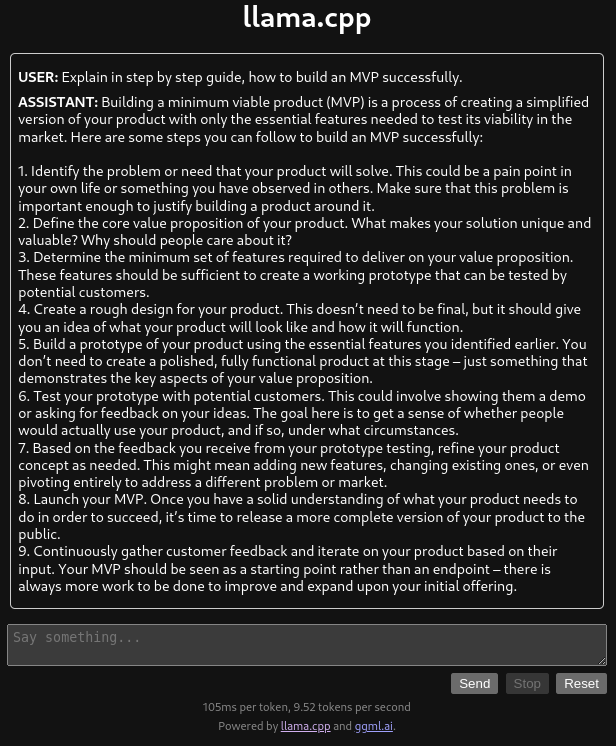
We may test the setup with a smaller model first. The prompt was about a guide for a successful MVP as it was the first thing that came to my mind. The results are not perfect but they are interesting.
Running Experiments
I tried a few things that I always wanted to try with a self-hosted LLM. I asked a few simple riddles that are easy to solve by humans but people reported that GPT-3.5 fails to solve them. I also tried to generate fantasy stories and I was surprised by the results. I even asked deep philosophical questions. The results are not perfect but they are interesting. I compared the results with GPT-3.5 and GPT-4.
The prompts were rewritten by GPT-4 as it has been shown that LLMs optimize the prompts: https://arxiv.org/pdf/2309.03409.pdf.
Some takeaways:
- GPT-3.5 is ultra-fast. It takes a few seconds to generate the results. The cost is about $0.01 for each experiment.
- GPT-4 is slower but still fast. The cost should be 20 to 30 times more than GPT-3.5. The results were beautiful.
- The Falcon 180B is super slow. I managed to output 0.75 tokens per second. With some napkin math, I estimate that the cost is ~7 times more than GPT-3.5 if it constantly outputs tokens.
You should choose GPT-3.5 if you want to generate a lot of text fast, GPT-4 if you want to generate high-quality content, and Falcon 180B if you want to generate content without leaking your data to a third party.
Note: GPT-3.5 is the model that is used behind ChatGPT.
Riddle A
There are two doors, one leading to freedom and the other to captivity. Each door is guarded by a guard. You know the guard who always tells the truth and the other guard who always lies. You can only ask one question to one guard to determine which door leads to freedom. What is the simplest question you ask the truth-telling guard?
GPT-3.5
The simplest question to ask the truth-telling guard would be: "Which door would the lying guard tell me leads to freedom?"
GPT-4
The trick to solving this puzzle is to ask a question that factors in the behavior of both guards. So, you don't necessarily specifically target the truth-teller.
You can ask either guard: "If I were to ask the other guard which door leads to freedom, what would they say?"
Here's why it works:
Let's say you asked this question to the guard that always tells the truth. He knows that the other guard would lie and point you to the door of captivity. Therefore, the truthful guard would tell you that the other guard would point you to the door of captivity.
Now, if you asked this question to the guard that always lies, he knows that the truthful guard would point you to the door of freedom. But since he is a liar, he tells you that the truthful guard would direct you towards the door of captivity.
So both guards point to the door of captivity in response to this question, and you would choose the opposite door, which leads to freedom.
Falcon 180B
What would the other guard say if I asked him which door leads to freedom?
Riddle B
There are three sisters in a room. Anna is reading a book. Alice is playing a game of chess. What is the third sister, Amanda, doing? Think step by step.
GPT-3.5
Based on the given information, the third sister, Amanda, is not mentioned. Therefore, I cannot determine what she is doing.
GPT-4
The text does not provide information on what the third sister, Amanda, is doing.
Falcon 180B
Amanda is playing chess.
Novel Idea for a Fantasy Story
Craft a unique concept for a fantasy story. Explain concisely what makes it innovative.
GPT-3.5
Title: "Shards of Serendipity"
Concept: In the land of Etherea, the universe is governed by an ancient celestial being known as the Serendipity Dragon. As the dragon weaves the tapestry of fate, it occasionally creates magical shards imbued with extraordinary powers. These shards are coveted by individuals known as "Weavers," who have the ability to see and manipulate the threads of destiny.
However, unlike traditional fantasy stories that focus solely on heroes or chosen ones, "Shards of Serendipity" shifts its narrative to the villains. The story delves into the lives of four disparate antagonists who unintentionally obtain the shards. Each shard not only grants them immense power but also unveils their untold pasts, deepest desires, and inner conflicts.
What makes "Shards of Serendipity" innovative:
Exploration of Villains: By centering the story around villains rather than heroes, "Shards of Serendipity" provides a fresh perspective on fantasy narratives. It humanizes the antagonists, delving into their motivations, traumas, and moral complexities. This innovation challenges the black-and-white portrayal of good and evil prevalent in traditional storytelling.
Dual Narratives: The story incorporates dual narratives, allowing readers to witness both the present struggles and the past experiences of each villain. This unique approach helps readers understand how events from their lives shaped their path toward villainy, thus challenging preconceived notions of morality and providing greater depth to their characters.
Character Development: Throughout the story, each villain is forced to confront their flaws and past mistakes, ultimately presenting them with an opportunity for redemption or transformation. This focus on character growth highlights the complexity of human nature, offering readers a nuanced exploration of redemption, forgiveness, and the blurred line between hero and villain.
Shard-based Magic System: The shards themselves introduce a captivating and innovative magic system. Each shard grants unique powers that reflect the inner struggles and desires of the villains. The Weavers, both heroes, and villains alike, must learn to harness and control their newfound abilities, leading to thrilling battles and creative displays of magic throughout the story.
Worldbuilding: The world of Etherea, governed by the enigmatic Serendipity Dragon, provides a rich backdrop for the story. By weaving elements of fate, destiny, and magic into the fabric of this fantastical world, "Shards of Serendipity" offers readers a fresh and immersive setting that adds depth to the narrative.
Overall, "Shards of Serendipity" stands out through its exploration of villains, dual narratives, nuanced character development, innovative shard-based magic system, and a captivating world. This fantasy tale invites readers to question traditional notions of good and evil while delving into the complex inner lives of its characters.
GPT-4
Concept: "The Weave of Time"
In a world where time isn't linear but woven like fabric, certain individuals - known as Time Weavers - have the ability to manipulate the threads of time. These Time Weavers can mend or unravel events to alter the past, present, or future. The main protagonist, a young and inexperienced Weaver, accidentally tears the fabric of time, causing parallel timelines and histories to bleed into each other.
What makes it innovative: This story takes the idea of time travel and manipulates it into something more complex: time-weaving. Instead of just traveling back and forth on a linear timeline, time becomes a more tangible, manipulable entity. This gives much more creative freedom in plot twists and character development as the protagonist must not only learn to control their own abilities but deal with the ethical implications of altering reality.
Falcon 180B
In a world where magic is real, but rare, a young girl discovers she has the ability to manipulate fire. She sets out on a journey to find others like her, and to learn more about her powers. This story is innovative because it explores the idea of magic being real, but rare. It also introduces a new type of magic user, someone who can manipulate fire.
Philosophical Question
How can I be certain that everyone else exists when I am unable to perceive the world through their experiences?
GPT-3.5
The philosophical question you are asking is commonly known as solipsism, which is the belief that only one's own mind is sure to exist. While it is impossible to prove beyond doubt that everyone else exists and experiences the world, there are several reasons to believe in the existence of others:
Empathy and shared experiences: Through empathy, we can understand and relate to the thoughts, emotions, and experiences of others. Our shared experiences, such as laughter, joy, pain, and sorrow, provide strong evidence for the existence of others who also feel and experience these things.
Consistency and coherence: The world appears consistent and coherent even when we are not directly perceiving it. Objects continue to exist even when they are out of sight, and events occur in a predictable manner. This suggests that there are other conscious beings who observe and interact with the world like we do.
Interactions and relationships: Our interactions and relationships with other people reinforce the notion that they exist as separate individuals with their own thoughts, emotions, and experiences. Our conversations, collaborations, and the impact we have on each other's lives support the reality of other minds.
Independent perspectives: Each individual has their own unique perspective on the world, their own subjective experiences, and their own thoughts. This diversity of perspectives suggests that other minds exist with their own independent existence.
Occam's Razor: Occam's Razor is a principle in philosophy that suggests that the simplest explanation is often the most likely. While it is possible to believe that you are the only mind that exists and that everything else is an illusion, it is a much more complex explanation than accepting that there are other conscious beings.
While these reasons may not provide absolute certainty, they provide reasonable justification to believe in the existence of others. Ultimately, the existence of other minds is an assumption we make based on our experiences and interactions with the world.
GPT-4
This philosophical question is associated with the concept of solipsism, which posits that only one's own mind is sure to exist, and everything outside of it could be a creation of the mind itself. However, it is widely considered to be an unproductive position due to its inability to be disproven.
As humans, we tend to trust in a shared reality because it is more practical and beneficial for our survival. Evidence of others' existence can be provided by physical interactions, shared experiences, emotional connections, and consistent feedback from our environment. You can be certain that others exist by trusting these pieces of evidence, along with basic principles of biology and evolution.
Additionally, science, which relies on observable and repeatable evidence, confirms the existence of others. From a societal standpoint, our interactions and relations with others have created civilizations, proving the existence of others.
But fundamentally, you cannot "prove" in an absolute sense that others exist independent of your perceptions as you cannot escape your own subjective experience. Yet, as the philosopher Rene Descartes pointed out: "I think, therefore I am." If we extend this logic to others, if they can think and communicate those thoughts, they also exist.
Falcon 180B
You cannot. You can only trust your own senses.
Conclusion
I hope that you enjoyed this article. I had a lot of fun running these experiments. I will continue to experiment with the Falcon 180B model and I will try to improve the results.
This article was generated with the assistance of AI and refined using proofing tools. While AI technologies were used, the content and ideas expressed in this article are the result of human curation and authorship.
Read more about this topic at: Importance is All You Need
Similar Posts
Try Llama2 Locally at No Cost
Looking to experience AI at its best? We try Llama 2, a new model from Meta, locally on our system for free! Transform your PC into a playground for next-gen AI, at absolutely zero cost!
- guide
- ai
- technical
Home VPN with WireGuard
Protect your privacy and security by setting up a home VPN with WireGuard. This guide will walk you through the process of creating a secure connection that safeguards your online activities, even on public Wi-Fi networks.
- guide
- security
- infrastructure
Agent Calibration
Every trade calibrates its tools before it trusts them. Coding agents need the same: a small AGENTS.md and a set of skills that set the baseline, so a project built by a non-technical founder can be handed over to professionals.
- ai
- technical
- guide